Key Takeaways & Findings
Include Thinking Tokens in Billing Costs: Billable output metrics encompass both generated tokens and internal reasoning (thinking) tokens.
Canary Deployment Pattern: Always run a 5% production canary alongside a fallback model to measure real-world performance before full migration.
Dual-SDK Architecture: Using CometAPI allows instant fallback to alternate providers (
Claude Opus 5.5orGPT-6 Astra) with zero code rewrites.
Moving a reasoning model into production requires more than functional API integration. Engineering teams must calculate operational costs, manage latency budgets, and build reliable fallback pathways.
1. Calculating the True Cost of Gemini 4 Argon
When projecting unit economics for Gemini 4 Argon, remember that internal reasoning tokens are billable output tokens:
Cost Breakdown Example (Per Task)
+-------------------------------------------------------------+
| Input Prompt Tokens (50,000)      -> $P_in * 50,000         |
| Thinking Trajectory (120,000)     -> $P_out * 120,000 (BILL) |
| Output Code (30,000)              -> $P_out * 30,000 (BILL)  |
+-------------------------------------------------------------+
2. Setting Up a Canary Deployment Routing Layer
To safely migrate workloads to gemini-4-argon, implement a simple ratio-based canary router in your service proxy:
import random
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("COMETAPI_KEY"),
    base_url="https://api.cometapi.com/v1"
)

def execute_resilient_prompt(prompt_text: str):
    # Route 5% of traffic to Gemini 4 Argon canary, 95% to baseline
    use_canary = random.random() < 0.05
    target_model = "gemini-4-argon" if use_canary else "gpt-4o"

    print(f"Routing request to: {target_model}")

    try:
        response = client.chat.completions.create(
            model=target_model,
            messages=[{"role": "user", "content": prompt_text}],
            max_tokens=2000
        )
        return response.choices[0].message.content
    except Exception as e:
        print(f"Primary model {target_model} failed! Executing rollback...")
        # Rollback target
        fallback_response = client.chat.completions.create(
            model="gpt-4o",
            messages=[{"role": "user", "content": prompt_text}]
        )
        return fallback_response.choices[0].message.content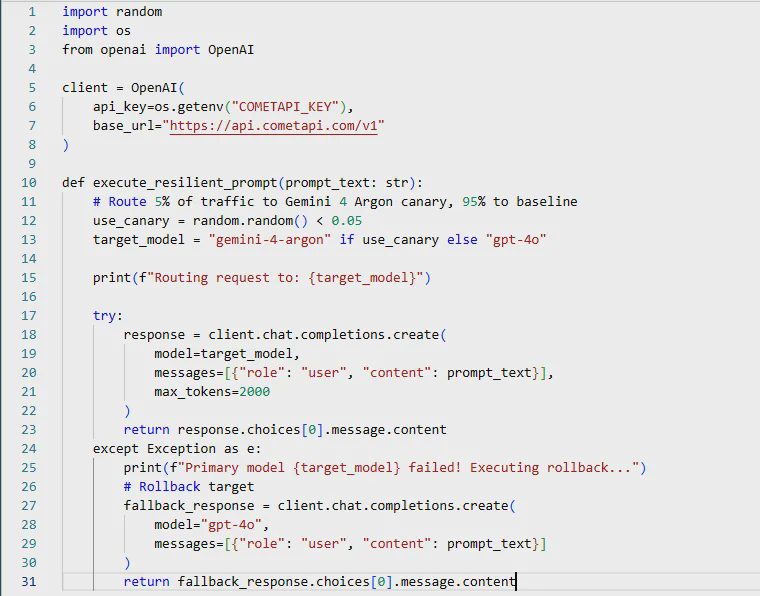
3. Production Readiness Checklist
Before scaling your Gemini 4 Argon implementation across enterprise services, complete these operational checks:
[ ] Environment variable authentication verified in clean isolated container
[ ] Token limits enforced via max_tokens to prevent runaway reasoning costs
[ ] Fallback target configured for high-traffic endpoints
[ ] Streaming implemented on all UI-facing client interfaces
[ ] Task accuracy monitored on a small evaluation benchmark set
Migration Decision Matrix
Metric Threshold | Action Standard |
|---|---|
Task Accuracy Increase > 15% | Complete migration to |
Latency Budget Exceeded | Adjust thinking parameters or enable streaming |
Cost Variance > 30% | Optimize prompt context size to reduce thinking overload |
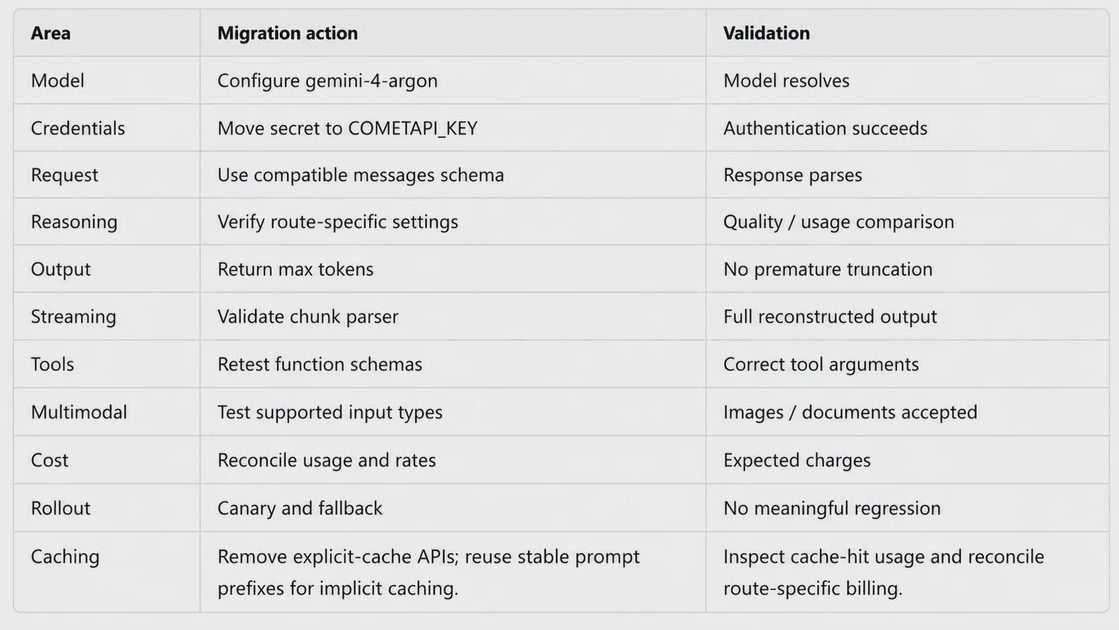
What Worked vs. What Failed vs. Production Changes
What Worked: Using a unified API proxy simplified testing without locking our startup into a single platform.
What Failed: Overlooking billable thinking tokens during initial cost estimation led to higher spending on complex multi-step prompts.
Production Changes: Set hard token limits and added automated latency monitoring across all production tasks.
"The demo is easy. Managing token costs and edge cases is where the real engineering begins."