Customer interviews produce pages of notes. The hard part is turning those notes into a small set of themes that a product team can act on without losing the original evidence. This post describes a Gemini-assisted workflow that keeps human judgment in control while accelerating the clustering and evidence-linking steps.
I have used this process after discovery cycles of eight to twenty interviews. The version below is the one that consistently produced themes the team could defend in roadmap discussions. The biggest risk in this kind of work is not that the model misses a theme; it is that the model invents coherence that the interviews do not actually support. Every step below is designed to make that risk visible and correctable.
Prepare the Notes First
Before any model call I do three things by hand:
Anonymize names and company identifiers
Split long transcripts into discrete observations (one idea per line)
Tag each observation with the interview ID so provenance is never lost
This preparation is non-negotiable. Gemini works better with clean, atomic inputs, and the tags make it possible to trace every theme back to source later. I also remove any of my own early interpretations that crept into the notes during the interview itself. The model should see the customer’s words, not my first-pass framing.
The preparation usually takes longer than the subsequent model calls. That is expected and correct. The quality of the themes is bounded by the quality of the observations.
Two-Pass Clustering
Pass 1 – Open clustering
I give Gemini the full list of observations and ask only for candidate theme names and the observation IDs that belong to each. No prioritization, no recommendations. The output is a draft map. I deliberately keep the temperature low and the instruction narrow so the model does not start inventing narrative.
Pass 2 – Human merge and split
I review the draft, merge overlapping themes, split themes that mixed distinct ideas, and discard noise. This step usually takes longer than the model call and is where most of the value is created. I also force myself to write a one-sentence definition of each final theme before moving on. If I cannot define it cleanly, the theme is not ready.
Only after the theme list is stable do I ask Gemini to pull the strongest supporting quotes for each final theme. Even then I re-read every quote against the original observation to confirm the model did not paraphrase in a way that changed meaning.
Evidence Table
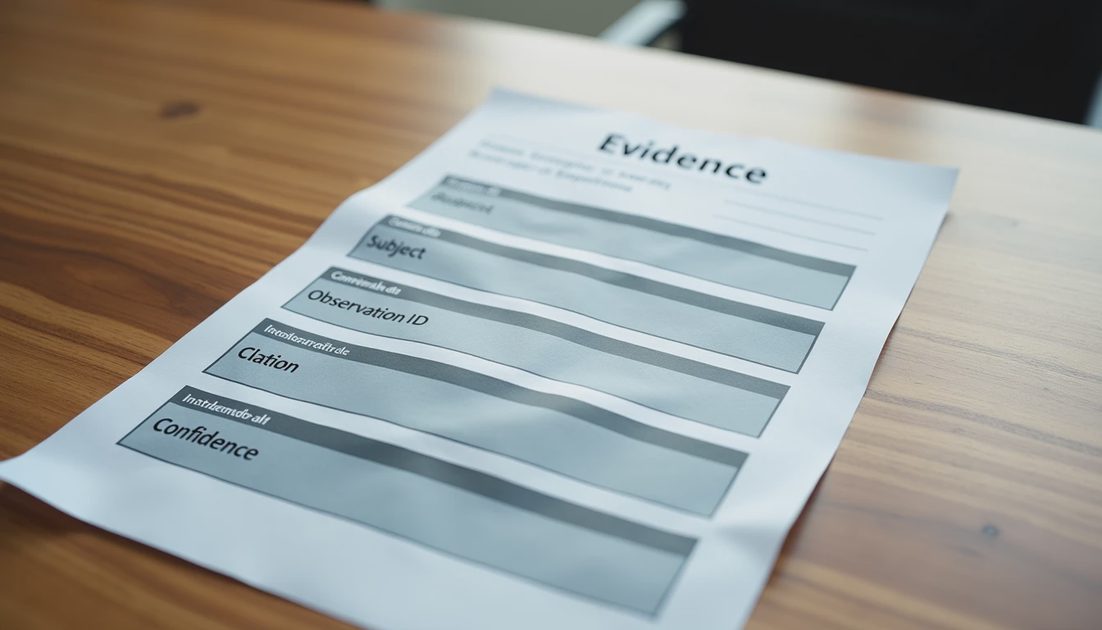
The final artifact I share with the team is a simple table:
Theme | Supporting Observation IDs | Strongest Quote | Confidence |
|---|---|---|---|
Onboarding friction | I-03, I-07, I-12 | “I gave up after the third screen” | High |
Pricing opacity | I-01, I-09 | “I still don’t know what I’m paying for” | Medium |
Integration gaps | I-05, I-11, I-14 | “It doesn’t talk to our CRM” | High |
Confidence is my judgment, not the model’s. Gemini never assigns the confidence score.
What I Refuse to Automate
Three decisions stay human:
Which themes are worth putting on a roadmap
How strongly the evidence supports each theme
Whether a theme should be dropped because the interviews were not representative
Gemini accelerates the mechanical work of grouping and retrieving quotes. It does not own the product judgment. I have seen teams skip the human merge step and ship the model’s first clustering directly into a strategy deck. The result looks tidy and is often wrong in ways that only become obvious weeks later when engineering starts building.
I also keep the original observation list and the final evidence table in the same folder. Anyone who questions a theme can walk back to the source quotes in under a minute. That traceability is what makes the themes defensible.
Common Failure Modes
Even with the two-pass process, three problems still appear:
The model groups observations that share vocabulary but not meaning
A single strong quote is treated as a theme when it appeared only once
Themes are named so abstractly that they become impossible to act on
When any of these occur I treat them as prompt debt. I add a short negative example to the clustering prompt and re-run only the affected section. Over several discovery cycles the prompt becomes tuned to the way my team’s interviews are actually written.
I tried it first. The two-pass structure and the evidence table are the parts worth copying. The exact prompt wording is secondary. The real product is the disciplined hand-off between model assistance and human judgment. Teams that keep that hand-off clear end up with themes they can actually defend when engineering asks “why are we building this?”
A useful follow-up habit: after a theme has been on the roadmap for a few weeks, revisit the original evidence table and ask whether new interviews have strengthened, weakened, or complicated the theme. The model can help surface candidate updates; the decision to change course stays human. That loop keeps the themes honest as more data arrives.
I also recommend writing a one-sentence “what would change our mind” note for each major theme. That note becomes the test for whether new evidence is material. Without it, teams can accumulate interviews without ever updating the themes that drive the roadmap.