Key Takeaways & Findings
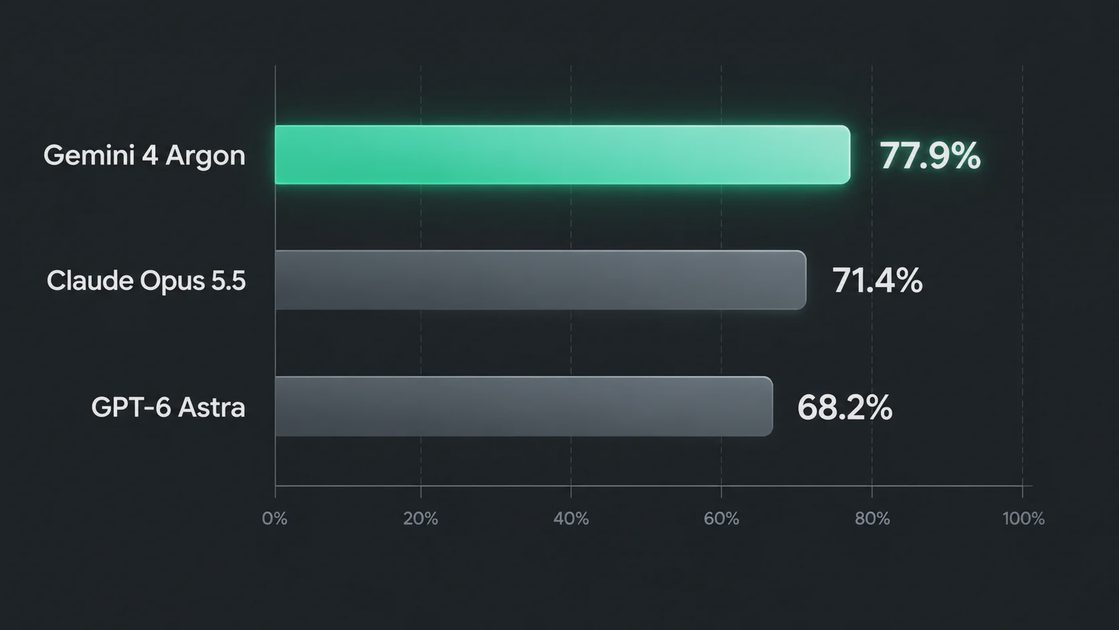
DeepSWE Benchmark Dominance: Gemini 4 Argon scores 77.9% on DeepSWE v1.1, demonstrating top-tier capabilities in autonomous software engineering.
Low Hallucination Rate: Arena evaluations show tool-hallucination rates dropping to ~0.10%, making it exceptional for factual execution.
Domain Limitations Exist: While dominant in software engineering, competitors edge out Argon on specific developer tests (e.g., GPT-6 Astra leads on FrontierSWE v2 with vs. Argon's ).
Evaluating foundation models requires cutting through promotional press releases and analyzing standardized benchmark data under real application workloads. In our tests at the lab, Gemini 4 Argon demonstrated distinct strengths alongside explicit limits.
1. Real-World Software Engineering Performance
In autonomous coding evaluations, performance across extended multi-file projects matters far more than simple single-function auto-completion.
DeepSWE v1.1 Benchmark Scores (%)
+-------------------------------------------------------------+
| Gemini 4 Argon               | 77.9% [LEADER]              |
| GPT-6 Astra                  | 68.2%                       |
| Claude Opus 5.5              | 71.4%                       |
+-------------------------------------------------------------+
Comparative Coding Metrics Matrix
Evaluation Benchmark | Gemini 4 Argon | GPT-6 Astra | Claude Opus 5.5 | Primary Metric Target |
|---|---|---|---|---|
DeepSWE v1.1 | 77.9% | 68.2% | 71.4% | Autonomous repo editing |
Vibe Code Bench | 91.9% | 88.4% | 89.1% | Rapid UI prototyping |
FrontierSWE v2 | 55.0% | 65.5% | 61.2% | Advanced architecture decisions |
Terminal-Bench 4.0 | 57.4% | 61.0% | 66.4% | CLI tool execution |
Takeaway: Argon is built for repo-level autonomous refactoring, but terminal-heavy shell operations may still benefit from model ensemble routing.
2. Enterprise Knowledge Work: The Vals Index
The Vals Index measures real-world task effectiveness across finance, legal, tax, and corporate decision-making, weighted by contribution to U.S. GDP.
Vals Index Aggregate: Gemini 4 Argon leads at 68.9%.
Specialized Dominance: Shows top performance across Harvey’s Legal Agent Benchmark and AutomationBench.
"A benchmark lead measures performance under a specific evaluation harness;
it does not replace human oversight in legal or financial production decisions."
— Field Note Verification Standard
3. Defensive Cybersecurity Evaluation
Google trained Argon with an explicit emphasis on defensive cybersecurity tasks, vulnerability discovery, and patch generation.
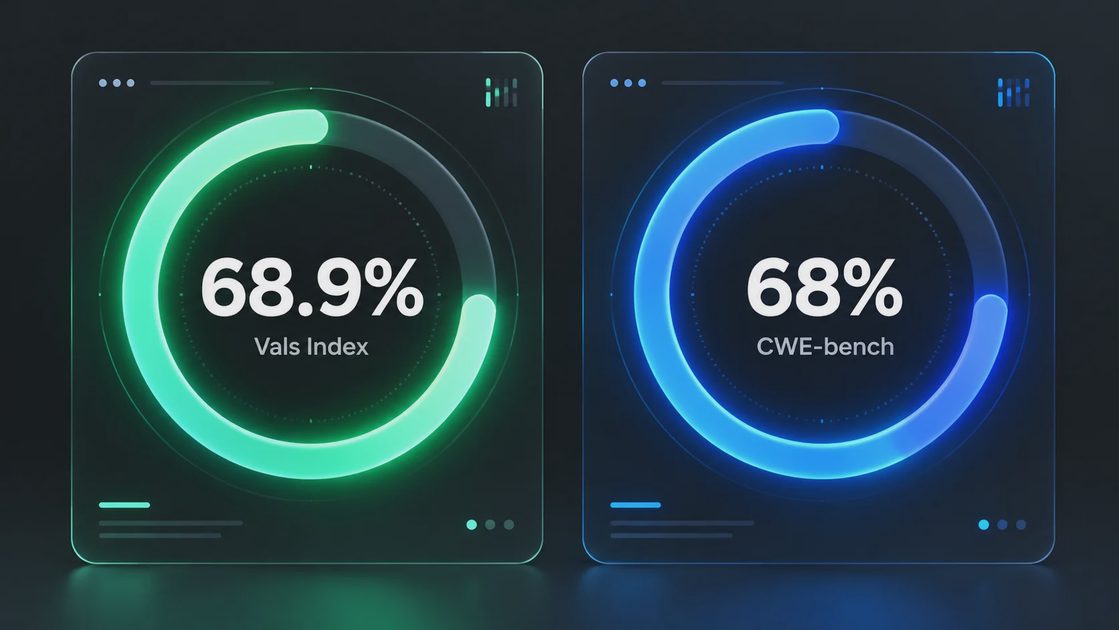
CWE-bench v1 Score Comparison
=============================================================
Gemini 4 Argon   : [=======================] 68%
GPT-6 Astra      : [=======================] 68%
Claude Opus 5.5  : [====================== ] 67%
=============================================================
Field Testing Observation: On internal vulnerability scanning benchmarks, Argon reliably generates valid patch scripts without hallucinating system APIs.
What Worked vs. What Failed vs. Production Changes
What Worked: High reliability on long-context refactoring runs with near-zero hallucination rates on structured API tools.
What Failed: Assuming Argon outperformed rivals on all coding tests led to regressions on complex shell command generation.
Production Changes: Routed CLI agent tasks through specialized models while reserving Argon for whole-repository refactoring.
In Part 4, we will finalize our implementation guide with production canary rollbacks, cost estimation, and migration best practices.