Getting Gemini to return valid JSON is easy in a demo and harder in production. The model will often produce almost-correct output that fails parsing, omits required fields, or invents extra keys. This post shows a practical pattern that combines clear schema instructions, server-side validation, and a controlled retry loop.
I use this pattern for any feature that feeds Gemini output into downstream code. The goal is not perfect generation on the first try. The goal is reliable, typed data by the time the function returns. Treating structured output as a reliability problem rather than a prompting problem has been the most useful mental shift.
Define the Schema First
Before writing any prompt I define the expected JSON shape in code, usually with Pydantic or a simple TypedDict. That schema becomes the single source of truth for both the prompt and the validation step.
Example schema for a meeting-action extractor:
from pydantic import BaseModel, Field
from typing import List, Optional

class ActionItem(BaseModel):
    description: str
    owner: Optional[str] = None
    due_date: Optional[str] = None

class ExtractionResult(BaseModel):
    decisions: List[str]
    open_questions: List[str]
    action_items: List[ActionItem]
The prompt then includes a short description of this shape and an explicit instruction to return only valid JSON that matches it.
Prompt Pattern That Improves Compliance
I keep the schema instructions near the top of the prompt and repeat the “return only JSON” constraint at the end. I also include one short positive example and one negative example when the model has previously failed on similar inputs.
A minimal template looks like this:
Return a JSON object that matches this schema exactly: ...
Do not include markdown, commentary, or code fences.
If a field is unknown, use null or an empty list.
Example of correct output: {...}
Example of incorrect output: {...}
The negative example is especially useful for stopping the model from wrapping the JSON in ```json fences. I also explicitly list the required top-level keys and state that any additional keys will cause the response to be rejected. That single sentence reduces the frequency of extra fields that break strict parsers.
When the schema contains nested objects or lists, I include one realistic nested example rather than a minimal empty one. The model appears to generalize better from a concrete instance than from an abstract description alone.
Validation and Retry Loop
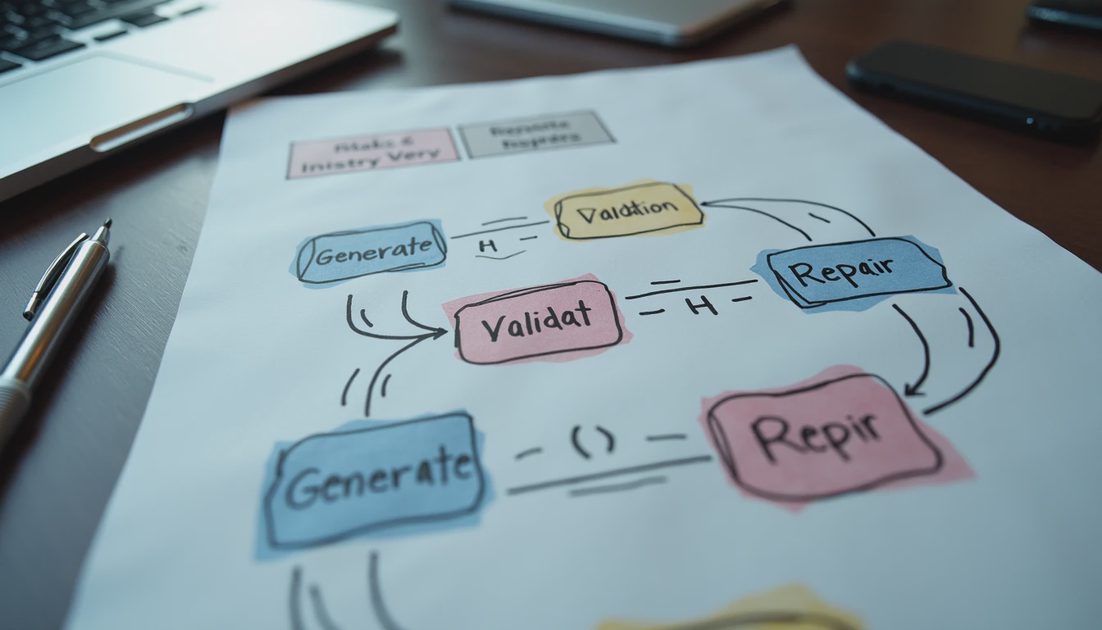
After the model responds I attempt to parse the text with the schema. On failure I do not immediately give up. Instead I construct a short repair prompt that includes the original schema, the invalid output, and the validation error message, then ask the model to fix it.
The loop is limited to two or three attempts. If it still fails I raise a structured error that the calling code can handle. Infinite retries hide problems; a small fixed budget surfaces them. I also log every failed attempt with the model name, the schema version, and the exact validation error. Over a few hundred calls those logs become the best source of prompt improvements.
One additional safeguard is to strip any leading or trailing markdown fences before the first parse attempt. Many failures are simply the model adding ```json despite instructions. A cheap string clean-up step recovers a surprising number of otherwise valid payloads.
Attempt | Action | Outcome if successful |
|---|---|---|
1 | Generate with schema prompt | Parse and return |
2 | Repair prompt with error details | Parse and return |
3 | Final repair or fallback to safe default | Return or raise |
What Worked / What Failed / What I Would Change
What worked
Keeping the schema in code and generating the prompt from it. Including explicit negative examples for common failure modes. Limiting retries so failures remain visible. Logging the raw model output and the validation error on every failure so patterns become visible over time.
What failed
Relying on the model’s “JSON mode” alone without validation. Early versions that retried more than three times and masked underlying prompt problems. Also, prompts that asked the model to “fix any issues” without showing the actual schema and error produced vague repairs.
What I would change in production
I would add metrics on first-try success rate and most common validation errors so the prompt can be improved systematically. I would also consider a cheaper Flash model for the repair attempts when the original call used Pro. Finally, I would expose a configuration flag that disables retries entirely during evaluation so that prompt quality can be measured cleanly.
I tried it first. You can adapt the same generate-validate-repair loop to any schema your application needs. The demo is easy. Reliable structured output is the real tutorial. Once this pattern is in place, adding new structured endpoints becomes mostly a matter of defining a new schema and writing a short description of it.