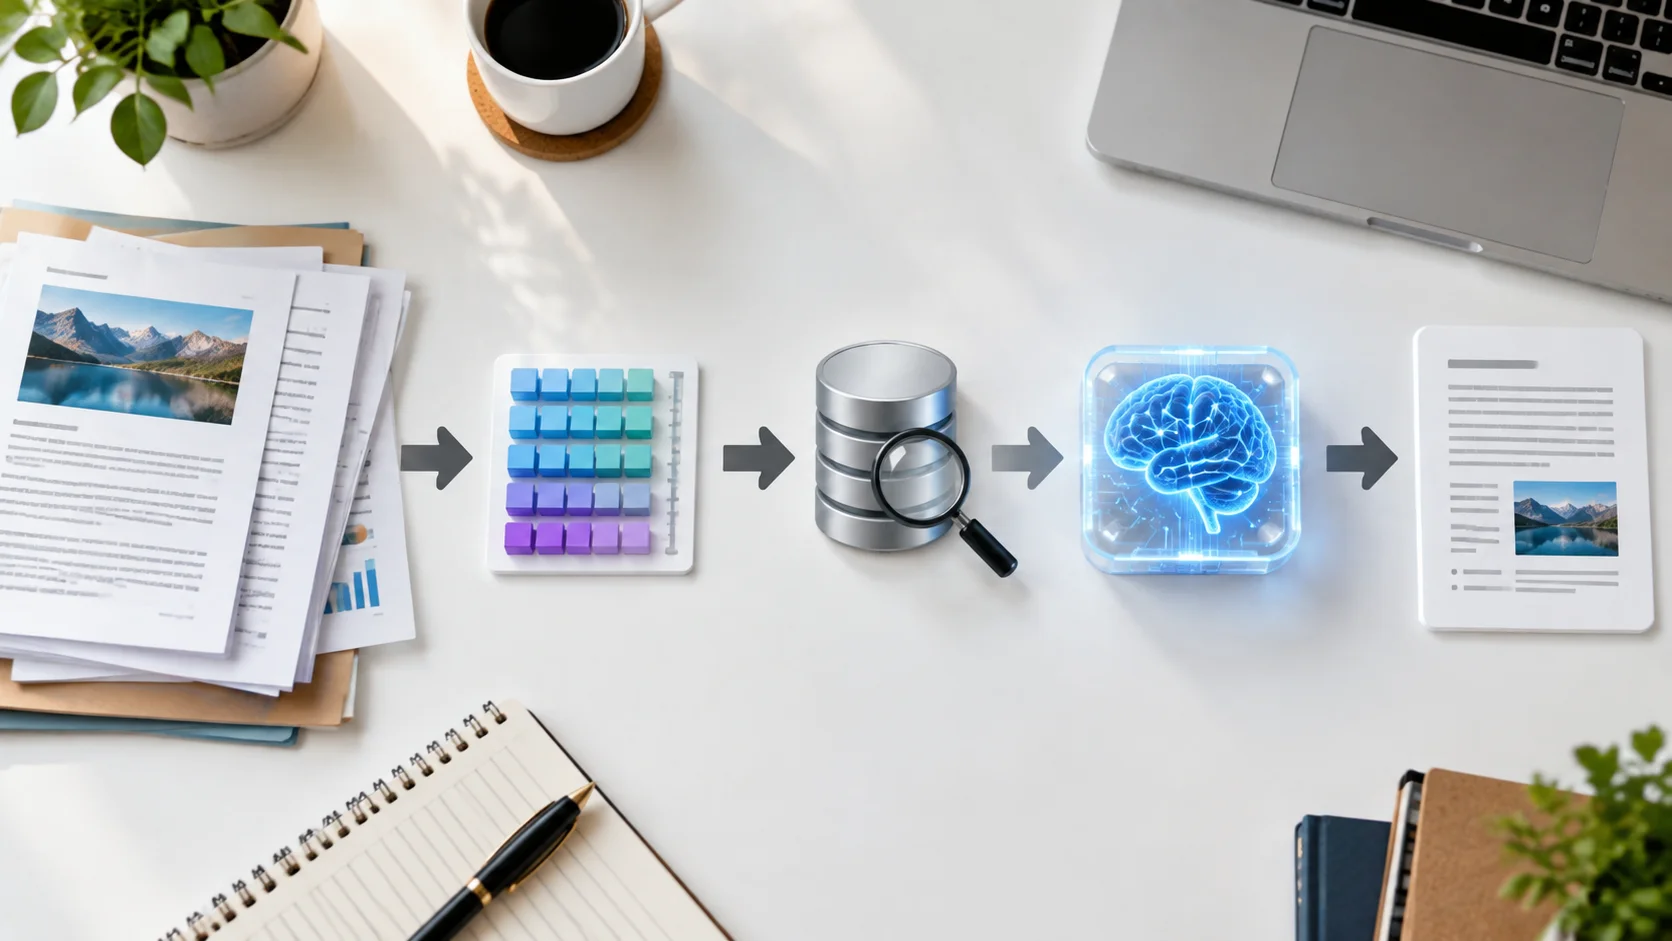
Retrieval-augmented generation (RAG) is often presented as a complex pipeline. For many internal tools a much simpler version is enough: embed a modest document set, retrieve the top few chunks, and stuff them into a Gemini prompt with clear instructions. This post shows the smallest version that still works reliably.
I built this pattern for an internal knowledge base of roughly 200 product and process documents. The goal was answer quality that beat pure parametric recall without requiring a full vector-database operations team. The system has been in daily use for several months. The parts that survived are the ones described below; the parts that added complexity without improving answer quality were removed.
The Minimal Components
A document store (in our case a folder of Markdown files)
An embedding model and a simple vector index
A retrieval function that returns the top-k chunks for a query
A Gemini prompt that receives the query plus the retrieved chunks
Basic citation of which chunks were used
That is the entire system. No agent loop, no multi-hop retrieval, no fine-tuning. Each component can be swapped later if needed, but starting with the simplest version that works has saved more time than any of the more elaborate architectures I tried first.
I also keep the document store under version control. When a document changes, the corresponding embeddings are refreshed in the same pull request. That discipline prevents the quiet drift that occurs when the index falls behind the source files.
Retrieval Before Generation
The quality of the final answer is bounded by the quality of the retrieved chunks. I spend more time on chunking strategy and retrieval evaluation than on prompt wording.
Practical choices that mattered:
Chunk size of roughly 300–500 tokens with modest overlap
Metadata filters (product area, document type) applied before vector search
A hard limit of three to five chunks in the prompt to control cost and noise
I evaluate retrieval separately from generation. If the right chunk is not in the top-k, no amount of prompt engineering will save the answer. My retrieval evaluation set is a list of questions paired with the document IDs that should be returned. I measure recall at k=3 and k=5. Only after those numbers are acceptable do I look at the generated answers.
Chunking is surprisingly consequential. Chunks that are too small lose surrounding context; chunks that are too large dilute the embedding and retrieve noise. The 300–500 token range was the result of testing, not a theoretical ideal. Your documents may need a different size.
Prompt Pattern
The prompt always follows the same skeleton:
Use only the information in the provided context to answer the question.
If the context is insufficient, say so explicitly.
Cite the source document IDs for every factual claim.
Context:
[chunk 1]
[chunk 2]
...
Question: {user question}
The explicit “if insufficient, say so” instruction reduced hallucinated answers more than any other single change. I also experimented with asking the model to quote short passages before answering; the extra step improved citation accuracy but increased latency. For our internal tool the simpler version was the better trade-off.
One additional rule I enforce in code: if the model returns an answer with no citations, the response is flagged for human review. That single check catches many of the remaining cases where the model drifts outside the provided context.
What Worked / What Failed / What I Would Change
What worked
Keeping the pipeline short. Evaluating retrieval on its own. Forcing citations. Using Flash for the generation step once retrieval was reliable. The explicit “say so if insufficient” instruction.
What failed
Early versions that retrieved ten chunks and let the model sort them out. The extra noise hurt more than it helped. Also, prompts that allowed the model to fall back to parametric knowledge when the context was thin. One early version tried to summarize the retrieved chunks before generation; the extra hop added latency and occasionally dropped important details.
What I would change in production
I would add a lightweight re-ranker after the initial vector retrieval and a simple feedback loop so that frequently cited chunks can be boosted. I would also store the exact chunks used for every answer so that audits are possible later. Finally, I would expose a “show sources” toggle in the UI so users can immediately see which documents grounded the answer.
I tried it first. You can implement the same five-component system with whatever embedding and vector library you already know. The demo is easy. Making retrieval reliable is the real tutorial. Once retrieval is solid, Gemini’s job becomes much simpler and much more trustworthy.
A practical next step after the basic system is working is to log every question, the retrieved chunk IDs, and whether the user found the answer useful. That log becomes the training data for improving both the retrieval index and the prompt. Without it, you are flying blind on which parts of the document set actually matter to users.
I also recommend starting with a deliberately small document set. Two hundred focused documents is easier to debug than two thousand noisy ones. Once the pipeline is stable and the citation rate is high, expanding the corpus is straightforward. Expanding a broken pipeline only multiplies the failure modes.